Mayank Singh

I am a Senior Machine Learning Engineer at Apple, working on generative models for 3D content creation. My research focuses on computer vision and 3D generation, including representations of geometry and appearance. My recent work, Luce, generates relightable 3D assets from a single image.

I received my master's degree in Robotics (MSR) from Carnegie Mellon University in 2022, advised by Prof. Katerina Fragkiadaki, and collaborated with Prof. Shubham Tulsiani.

Previously, I worked at Adobe's Media and Data Science Research Labs in India and collaborated with Prof. Vineeth N. Balasubramanian. I graduated from the Indian Institute of Technology Kharagpur in Mathematics and Computing. My earlier research explored adversarial machine learning and few-shot learning.

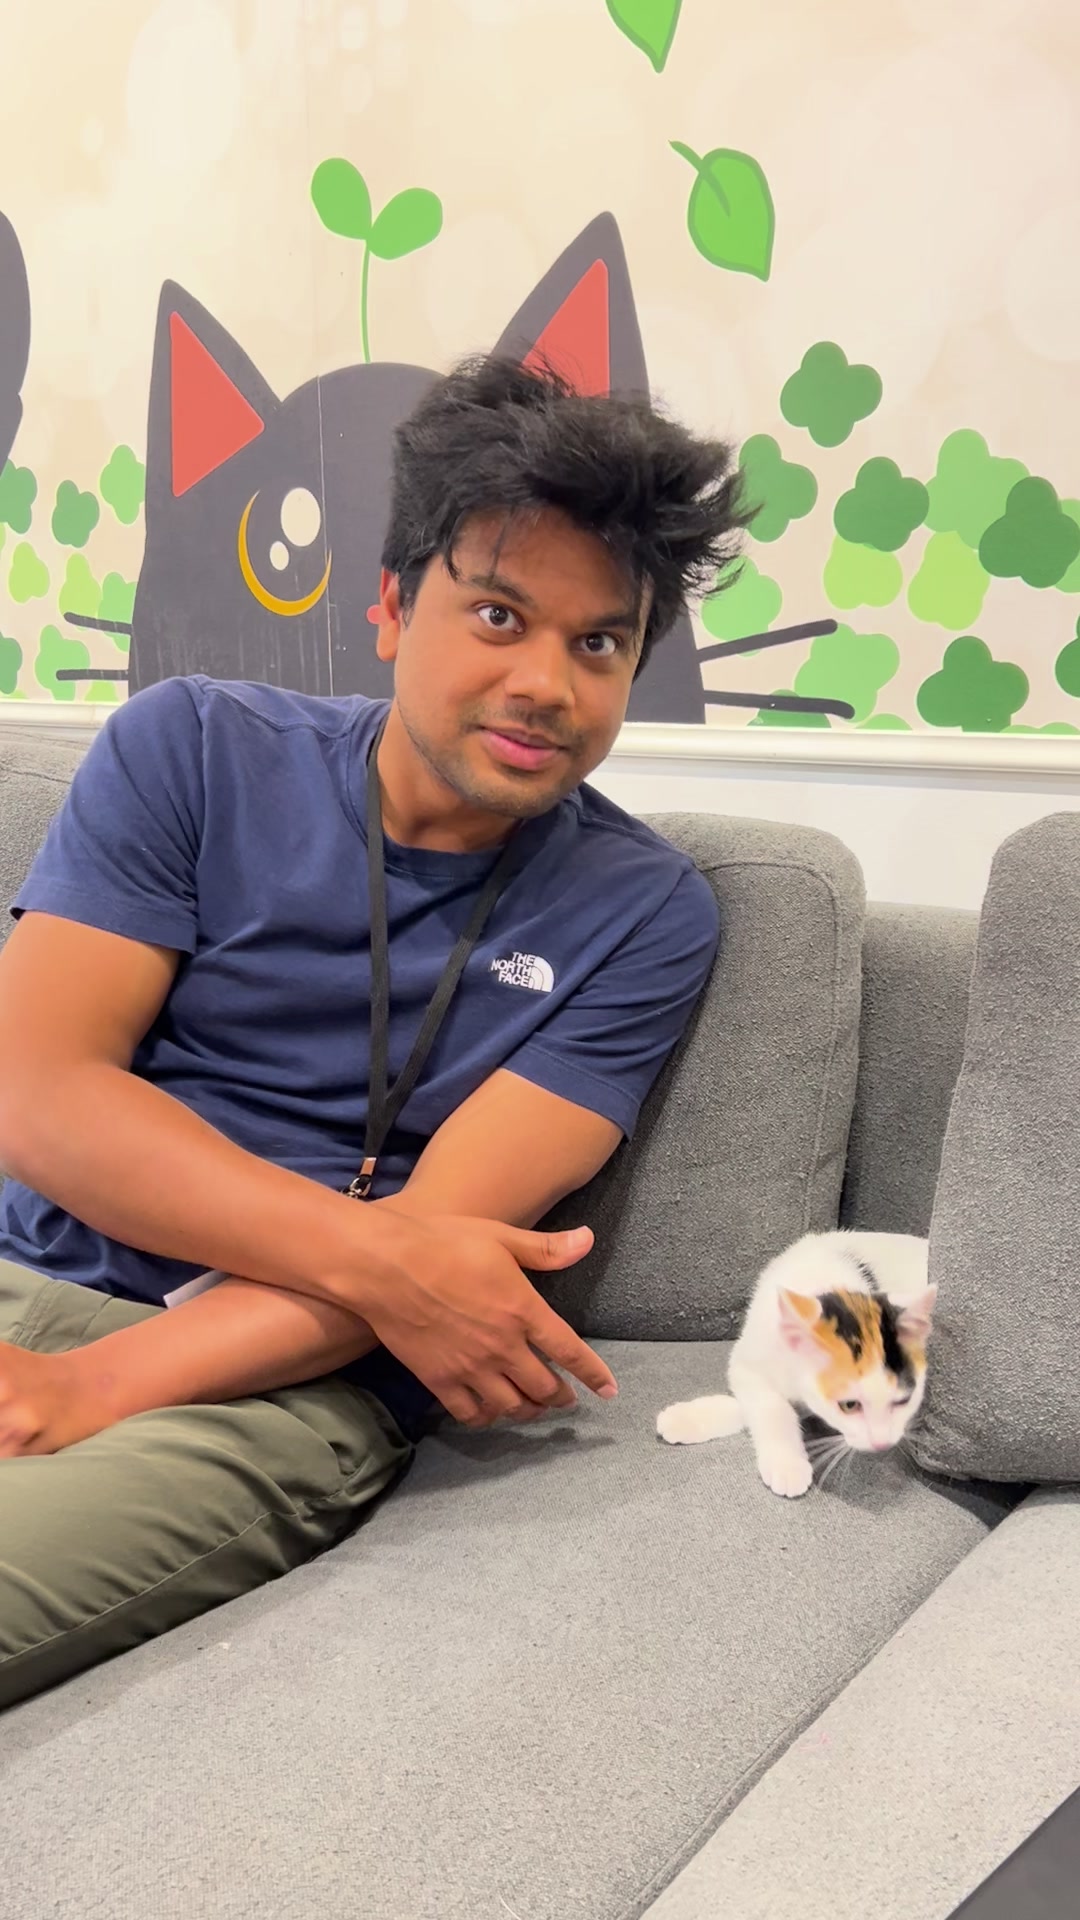
Mayank Singh sitting beside a kitten

Selected Publications

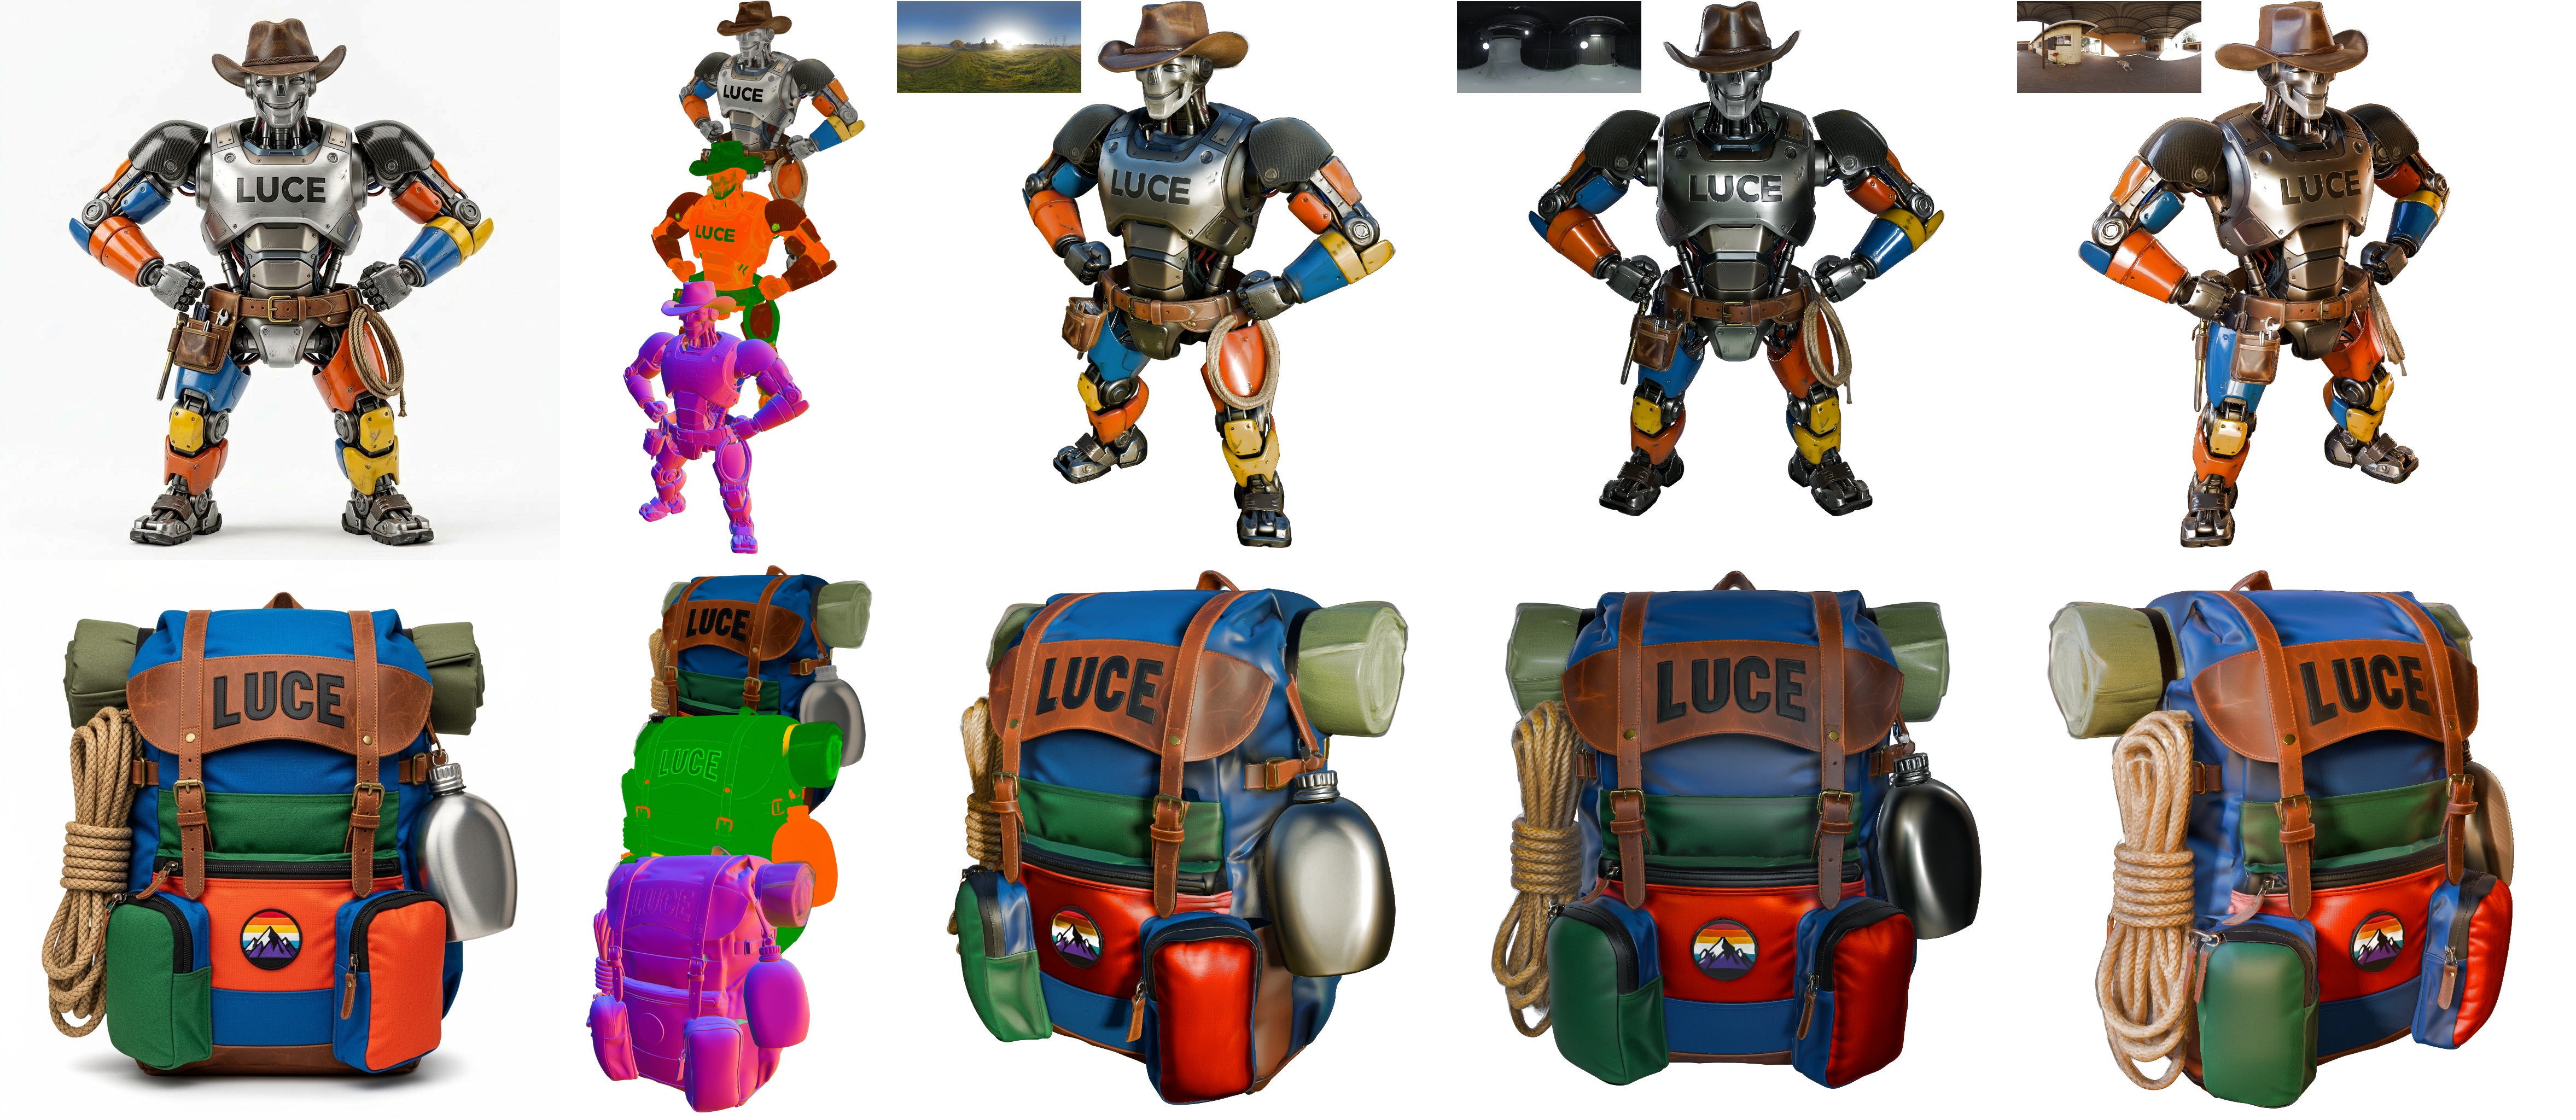
Luce results for a robot and a backpack. From left to right: conditioning image, physically based Gaussian representation, and renders under three different lighting environments.
Input · PBR GS · Relit renders
View full-size image

Luce: Relightable Gaussians for 3D Asset Generation

Mayank Singh, Michele Stoppa, Alvise Memo, Rui Yu, Sree Harsha Kalli, Srimanth Gunturi, Muhammad Ahmed Riaz, Behrooz Shahsavari, Waleed Abdulla, David E. Jacobs

Luce generates relightable 3D assets from a single image using a Gaussian representation of geometry and physically based materials. It preserves fine appearance details and produces PBR Gaussians, with optional textured mesh output.

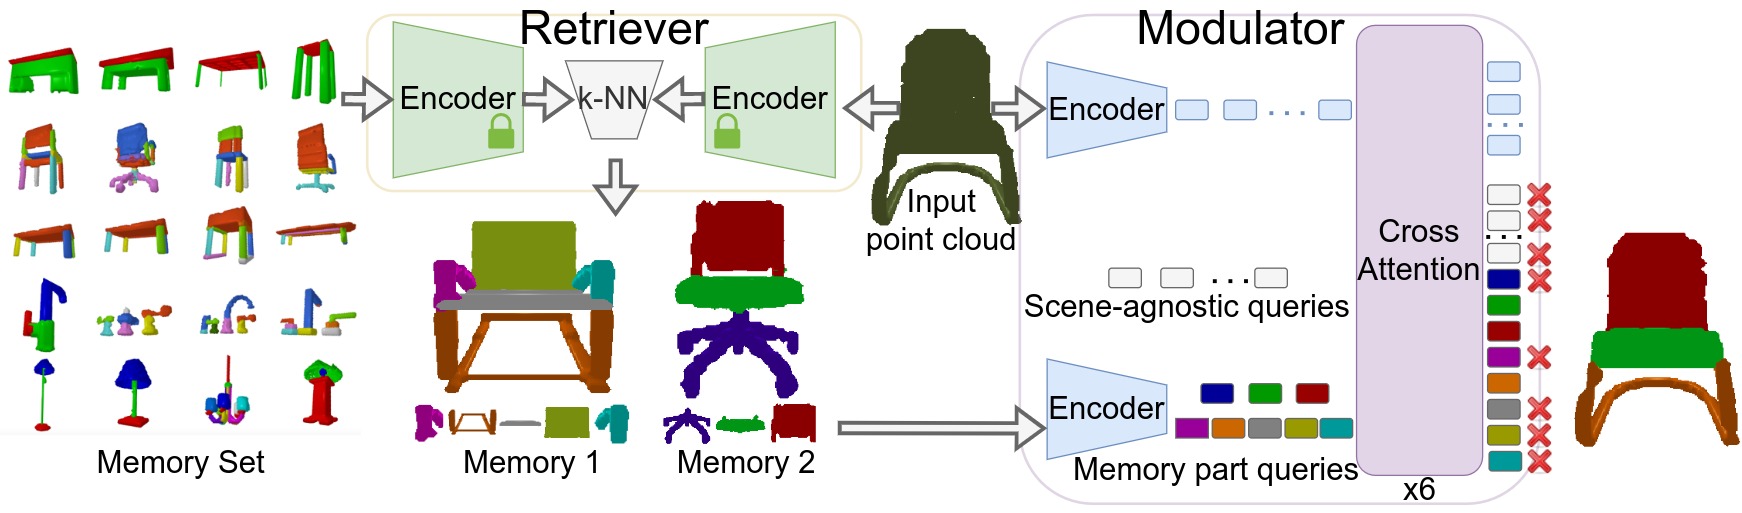
Analogical Networks architecture for few-shot 3D part parsing

Analogy-Forming Transformers for Few-Shot 3D Parsing

Nikolaos Gkanatsios*, Mayank Singh*, Zhaoyuan Fang, Shubham Tulsiani, Katerina Fragkiadaki

We present Analogical Networks, a model that casts fine-grained 3D visual parsing as analogy-forming inference: instead of mapping input scenes to part labels, which is hard to adapt in a few-shot manner to novel inputs, our model retrieves related scenes from memory and their corresponding part structures, and predicts analogous part structures in the input object 3D point cloud, via an end-to-end learnable modulation mechanism.

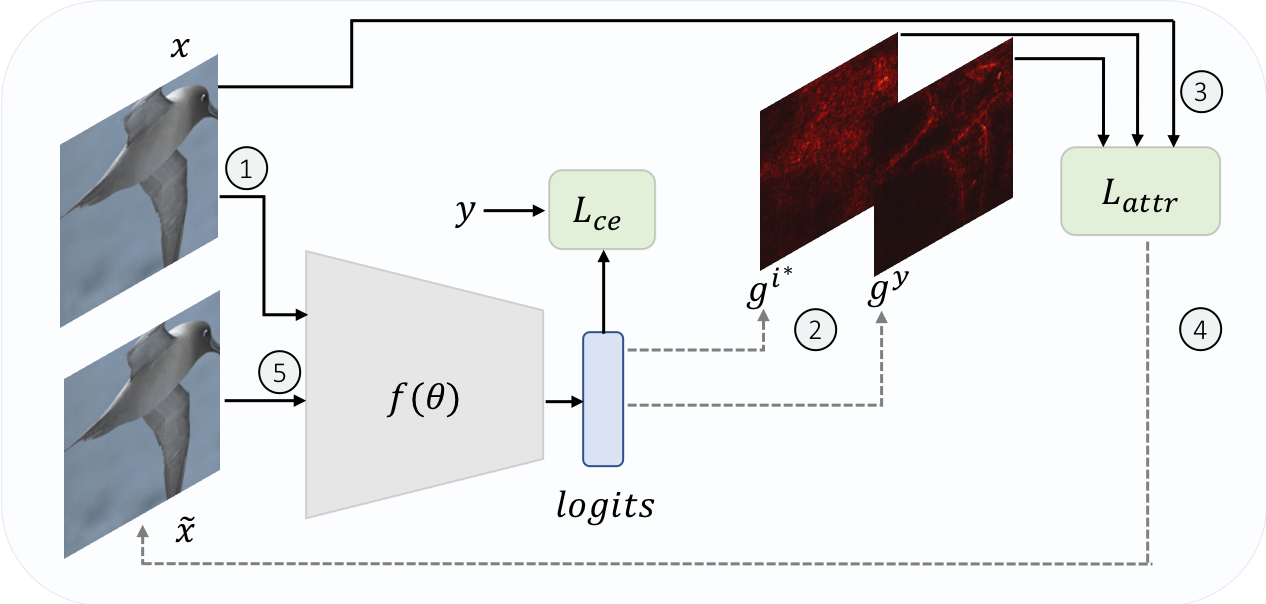
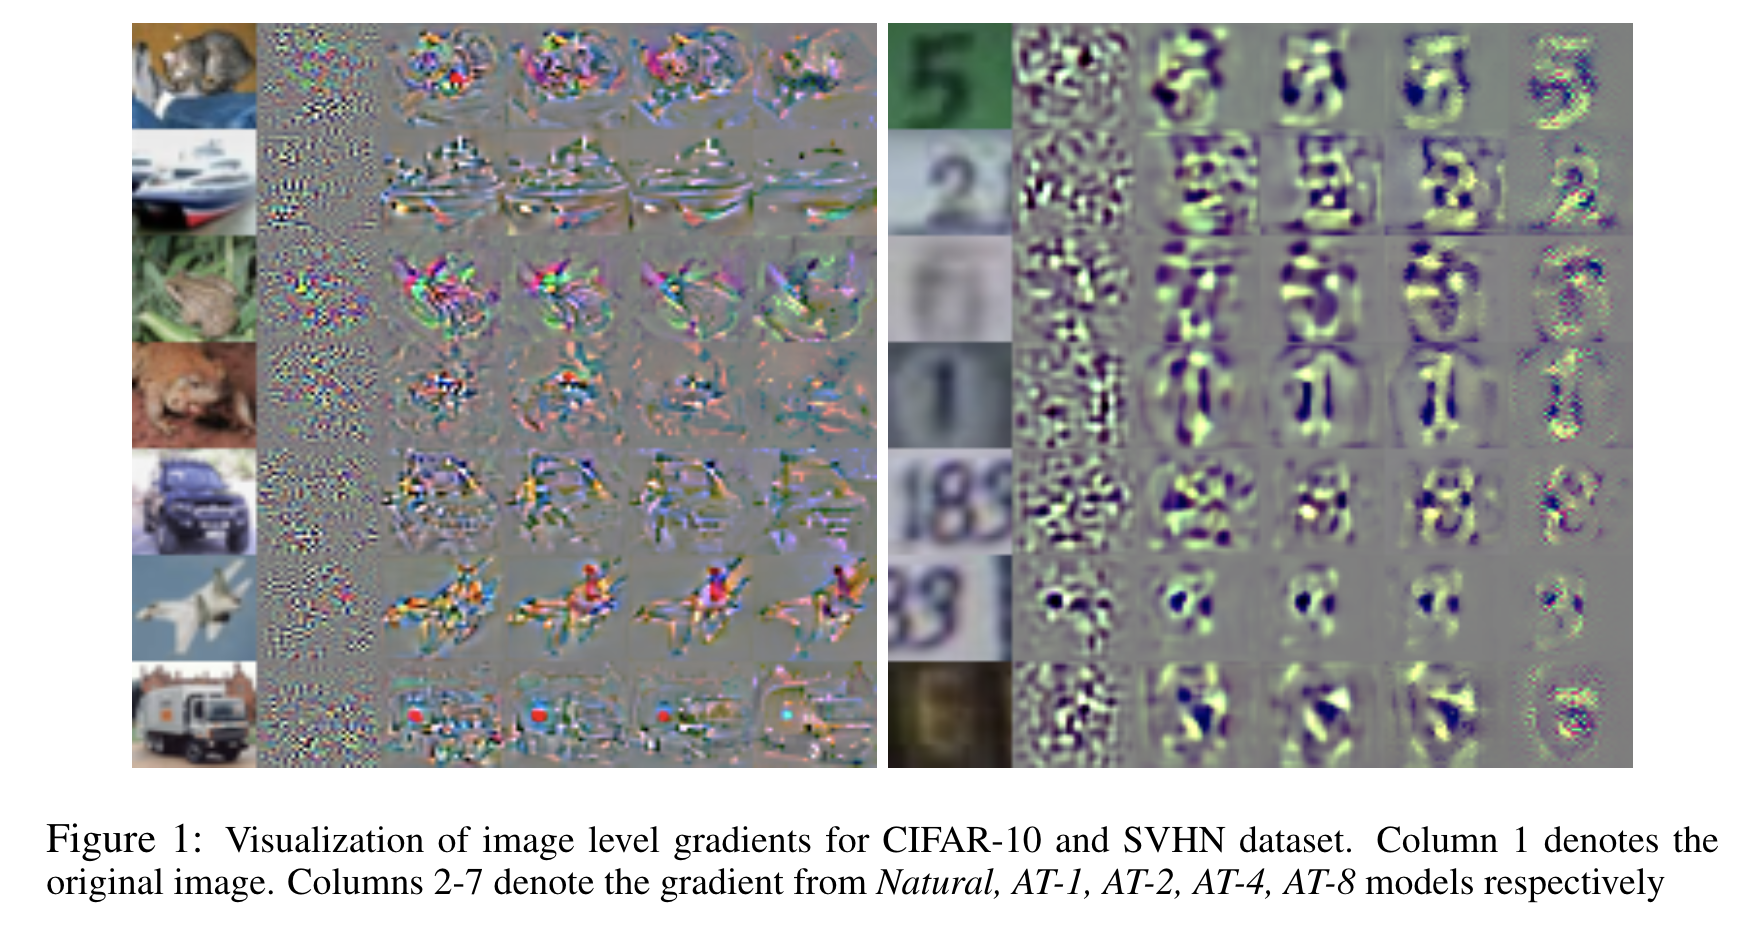
Attribution maps from attributional robustness training

Attributional Robustness Training using Input-Gradient Spatial Alignment

Mayank Singh*, Nupur Kumari*, Puneet Mangla, Abhishek Sinha, Vineeth N Balasubramanian, Balaji Krishnamurthy

We propose a robust attribution training methodology ART that maximizes the alignment between the input and its attribution map. ART induces immunity to adversarial and common perturbations on standard vision datasets. It achieves state-of-the-art performance in weakly supervised object localization on CUB dataset.

* denotes equal contribution